How to Stop a Runaway n8n Loop From Burning Your OpenAI Budget
How n8n workflows loop overnight, what one runaway loop costs by the hour, and the five guards that stop it before it burns a client’s OpenAI budget.
On this page
A runaway n8n loop is stopped by five guards set before launch: capped retries, a capped agent, a dedupe check on triggers, a workflow timeout and a spend ceiling for that one client. Most agencies set none of them, and find out at 8 AM.
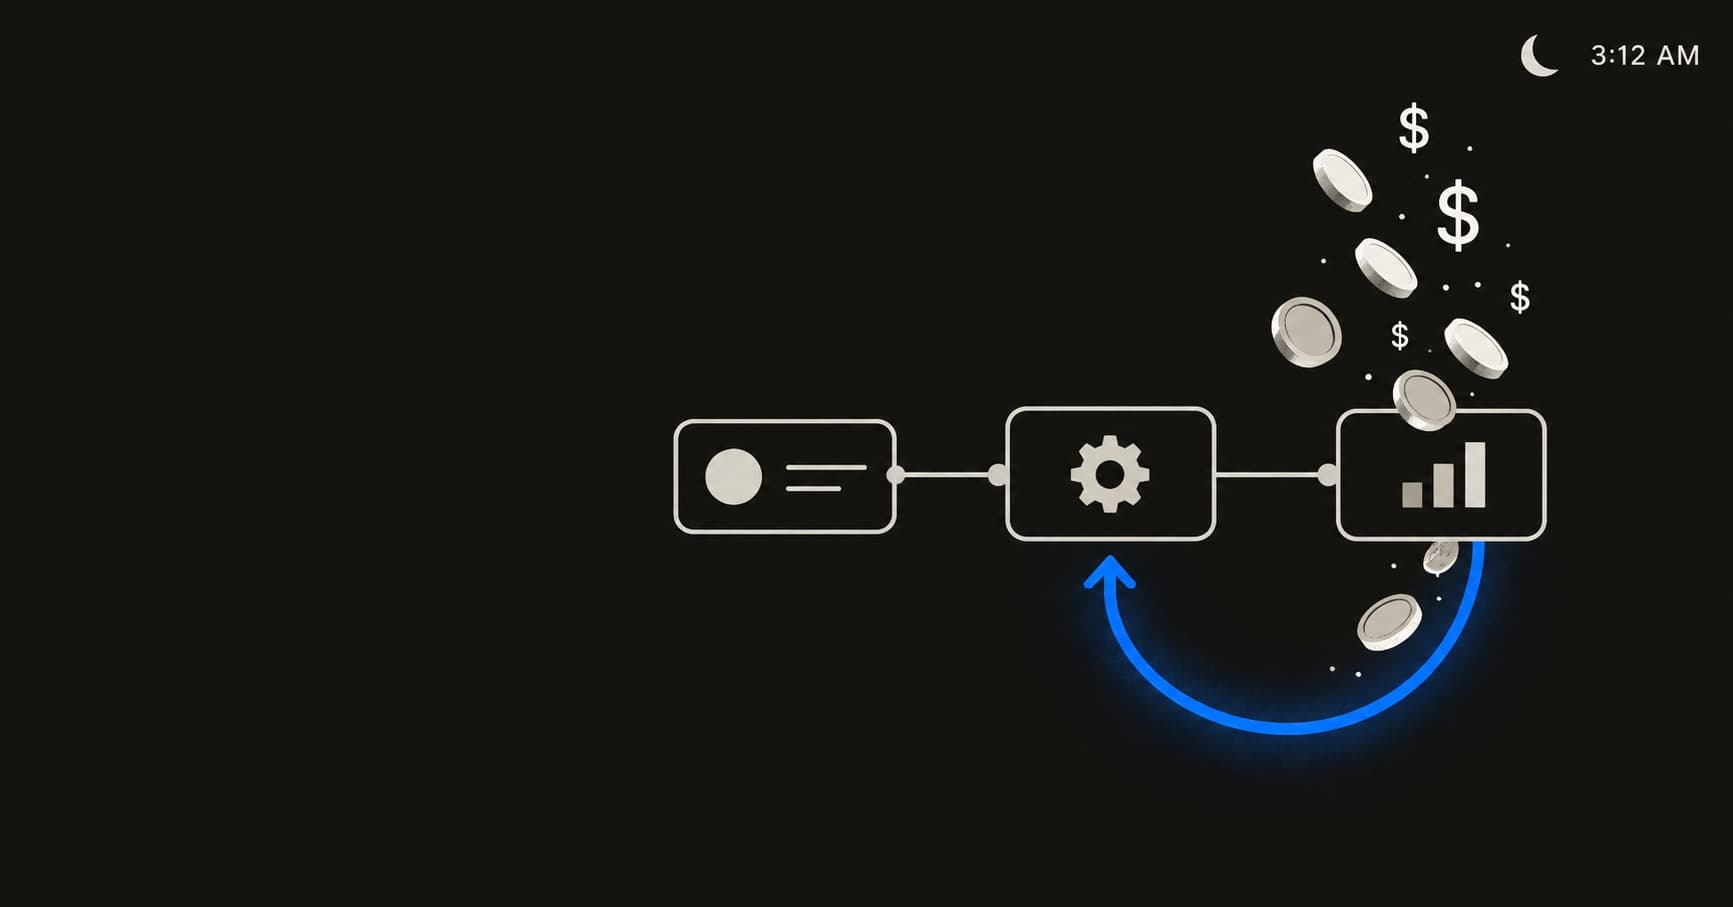
Here is the pattern. A workflow that summarizes a client’s inbound leads ships on Friday. At 11 PM the CRM API starts returning errors. The OpenAI node retries, the error branch re-triggers the workflow, and each pass sends the same 6,000-token prompt again. By morning the account shows over $400 of spend for a client who pays a $300 monthly retainer.
Nothing was broken in the prompt or the model. The workflow did exactly what it was told, as fast as it could, all night. This post covers how those loops form in n8n, what one costs hour by hour, and the settings that stop it.
The four ways n8n workflows loop
Most runaway bills come from one of four patterns, and each one resends a paid prompt without anyone noticing.
Four ways an n8n workflow loops
Each one sends the paid prompt again
1 Retry storm
2 Error handler re-runs the job
3 Webhook echo
4 Agent spin
- Retry storm. Retry On Fail is on for a model node that processes a batch. When the API after it goes down, every item retries, and every retry resends the full prompt. One more trap: a reported n8n issue shows Retry On Fail being skipped when On Error is set to a Continue option, so the behavior you configured may not be the one you get (GitHub #9236).
- Error handler re-runs the job. An Error Trigger workflow calls the main workflow again with Execute Workflow, to be helpful. If the cause is still there, the run fails, fires the error workflow, and starts again. No retry cap applies, because each run is a new execution.
- Webhook echo. The workflow updates the CRM record that triggered it. The CRM fires its “record updated” webhook. The workflow runs again on the same record, forever, one fresh execution at a time.
- Agent spin. An AI Agent that can’t complete its task keeps calling tools until it hits Max Iterations. Agents nested as AI Agent Tool nodes each carry their own cap, so the calls can multiply.
What one night costs
A loop that resends one mid-size prompt every three seconds costs about $45 an hour, and passes a $300 retainer in under seven hours.
One looping workflow, overnight
Cumulative spend at about $45 an hour
| Time | Calls | Spend |
|---|---|---|
| 11 PM | 0 | $0 |
| 12 AM | 1,200 | $45 |
| 1 AM | 2,400 | $90 |
| 2 AM | 3,600 | $135 |
| 3 AM | 4,800 | $180 |
| 4 AM | 6,000 | $225 |
| 5 AM | 7,200 | $270 |
| 6 AM | 8,400 | $315 |
| 7 AM | 9,600 | $360 |
| 8 AM | 10,800 | $405 |
The math is short. A 6,000-token prompt with a 500-token answer costs about $0.0375 on a model priced at $5 input and $15 output per million tokens. With a 1-second wait between tries and a 2-second response, the loop fires about 1,200 times an hour. Plug in your own model’s prices: the shape stays a straight line up, and nothing in n8n bends it.
The cost is rarely the worst part. You either absorb the $405, or you send an invoice for work the client never asked for and can’t see.
The five guards to add in n8n
Each guard sits where its loop starts, so a failure stops one step in instead of running all night.
Where each guard sits
From the trigger to the provider. Numbers match the list below.
Trigger
Webhook or poll
Dedupe. Skip IDs already processed, and your own integration’s updates
Workflow run
And its error workflow
Timeout. A little above the normal run time; the error workflow only alerts
AI Agent
And nested agent tools
Max Iterations. 5 to 8 while you build
Model node
Every call is billed
Retry cap. 2–3 tries, 1,000 ms apart, no retry on a 400 or 401
Client key
One per client
Ceiling. A monthly cap, with alerts at 50% and 80%
Provider
OpenAI, Anthropic…
- Cap retries on every model node. Open the node, go to Settings, turn on Retry On Fail, and set Max Tries to 2 or 3 with Wait Between Tries at 1,000 ms or more (n8n docs). Don’t retry errors that can’t succeed: a 400 or 401 fails every time. Send real failures to the error output and stop there.
- Cap every AI Agent. In the agent’s options, set Max Iterations. Keep it at 5 to 8 while you build, and raise it only when a test shows the task needs more (n8n docs). Set it on nested AI Agent Tool nodes too.
- Dedupe before the model call. Store each record ID with its last-processed timestamp (a Data Table, Redis or a sheet) and skip anything already seen. On CRM webhooks, also skip updates made by your own integration user: that alone kills the webhook echo.
- Set a workflow timeout, and keep the error workflow passive. In Workflow settings, set a timeout a little above the normal run time. Your error workflow should alert you on Slack or email. It should never call the main workflow again.
- Give each client a ceiling. One key per client, a monthly cap on it, and an alert at 50% and 80%. A cap only protects a client if no other client shares the key. The next section explains why the provider’s own limits rarely give you that.
Why provider limits won’t save one client’s budget
OpenAI’s spend limits help, but they are built for a company running its own product, not an agency running twenty clients.
OpenAI now lets you set a monthly spend limit on the organization and on each project, and enforce it as a hard limit. Once a project hits it, requests fail with a 429 and the project_spend_limit_exceeded code (OpenAI docs). Three gaps remain for agencies:
- The limit is monthly. A loop can spend the whole month’s allowance in one night. You are protected from the second $400, not the first.
- It only isolates what you split. If five clients share one project or one key, the hard limit stops all five when one of them loops. Per-client protection means one project and one key per client, on every provider you use.
- Each provider is its own island. The same client may run on OpenAI, Anthropic and Perplexity. You configure, monitor and reconcile three sets of limits, and no single view shows that client’s total.
So the provider limit is your last line, not your first. Set it, then rely on the guards inside the workflow, plus a per-client ceiling that sits in front of every provider. You can build that ceiling yourself (a small proxy or a spend log the workflow checks), or use a tool that issues one key per client project with its own budget, such as keyone.
Pre-launch checklist for any client workflow that calls an LLM
Run this before a workflow goes live, and again when you change a trigger or add an agent.
- Retry On Fail is capped at 2–3 tries with at least 1,000 ms between them, on every node that calls a model
- No node combines Retry On Fail with a Continue option under On Error (check what actually happens on your n8n version)
- The error workflow alerts you; it never re-runs the main workflow automatically
- Every AI Agent has Max Iterations set, low (5–8) while you test
- Webhook and polling triggers check an ID against a store before calling the model
- The workflow has a timeout in its settings
- Loop Over Items has a hard exit condition, not just “no more items”
- This client has its own key and its own monthly ceiling, below what one bad night would cost
- An alert fires at 50% and 80% of that ceiling, to a channel someone reads at night
- You ran the workflow once with the downstream API forced to fail, and watched what it did
The last item is the one that catches loops. Break the thing the workflow depends on, on purpose, and see whether it stops or spins.
